Key takeaway
- Apache Airflow explained: Airflow 3 architecture, executors, benefits, install steps, best practices, governance and when to choose another tool.
Apache Airflow is an open-source platform for developing, scheduling and monitoring workflows. You write each workflow as Python code, Airflow runs its tasks in dependency order, and a web UI shows what ran, what failed and what to rerun. The current release line is Airflow 3 (3.4.0 at the time of writing), and Airflow 2 reached end of life on 22 April 2026, so new work should start on Airflow 3.
For enterprise leaders the question is where Airflow fits. It suits scheduled batch pipelines, machine learning training runs and AI or LLM workloads with a clear start and end. It is not a streaming engine. This guide covers architecture, what changed in Airflow 3, benefits, installation, best practices, executors and governance. For a tool comparison, see Airflow vs Azure Data Factory; for the wider topic, see workflow orchestration.
What is Apache Airflow and what is it used for?
According to its documentation, Airflow handles traditional scheduled or event-triggered batch pipelines, machine learning training and AI or LLM workloads. A workflow is a Dag (directed acyclic graph): a model that bundles the schedule, tasks, dependencies and callbacks. Tasks are discrete units of work, defined with operators such as BashOperator or decorators such as @task, and dependencies set with >> control the order. Because Dags are Python, they can be reviewed, tested and versioned like any other code.
| Use case | Where Airflow fits | Note |
|---|---|---|
| ETL and ELT | Schedules extract, transform and load steps and their dependencies | A data pipeline is the unit Airflow coordinates; the heavy compute usually runs in the warehouse or engine it calls |
| Machine learning | Orchestrates data preparation, training and deployment steps | Airflow orchestrates the steps; training runs elsewhere |
| AI and LLM workloads | Runs scheduled or event-triggered steps around models and data | Named in the Airflow documentation as a supported workload type |
| Data warehouse loading | Triggers loads and checks on a schedule | Use provider packages for the target system |
| Operational jobs | Schedules recurring jobs with retries and alerts | Keep jobs idempotent so retries are safe |
How does Apache Airflow work in version 3?
An Airflow 3 deployment is a set of cooperating components. The scheduler triggers workflows and hands tasks to an executor, a Dag processor parses Dag files, an API server serves the UI and REST API, and a metadata database stores state. According to its documentation, the table below shows what each component does.
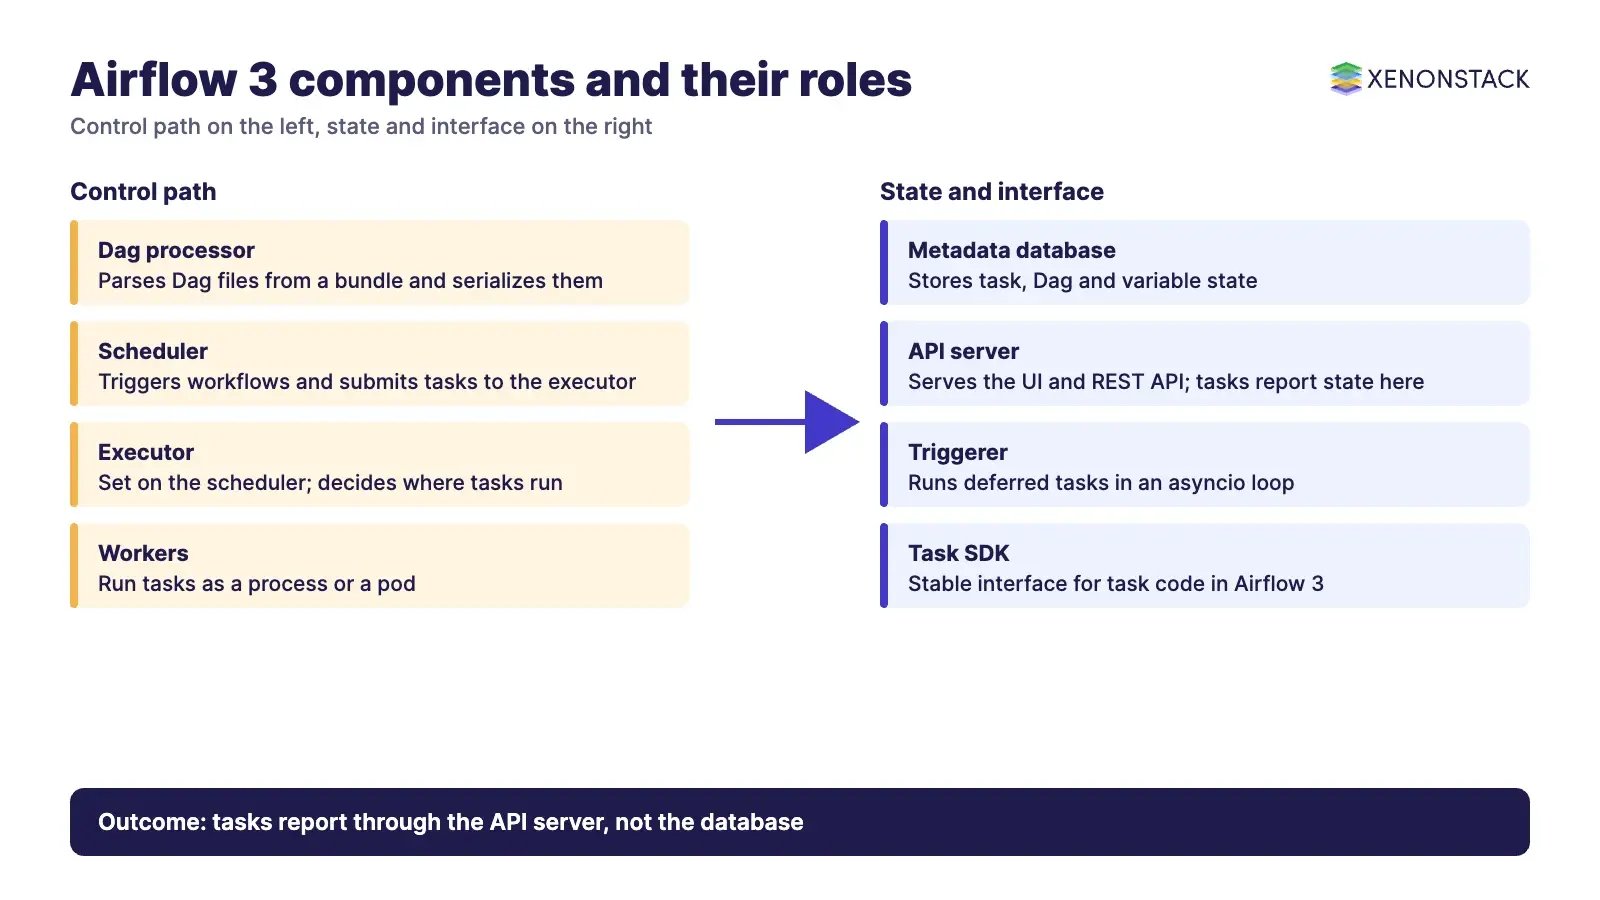
| Component | What it does (per the Airflow docs) | Required? |
|---|---|---|
| Scheduler | Triggers scheduled workflows and submits tasks to the executor | Yes |
| Dag processor | Parses Dag files from a Dag bundle and serializes them into the metadata database | Yes, in all Airflow 3 deployments |
| API server | Serves the REST API and UI; tasks also use it to report state, so they need no direct database access | Yes |
| Workers | Execute tasks handed over by the scheduler, as a long-running process (CeleryExecutor) or a pod (KubernetesExecutor) | Optional |
| Triggerer | Runs deferred tasks in an asyncio event loop | Only if you use deferred tasks |
| Metadata database | Stores the state of tasks, Dags and variables; usually PostgreSQL or MySQL | Yes |
| Executor | A property of the scheduler, not a separate process | Yes |
Source: Airflow architecture overview and the Airflow 3 upgrade guide.
What changed in Airflow 3?
Airflow 3.0 was first released on 22 April 2025. The project's release post lists DAG versioning, backfills run by the scheduler, event-driven scheduling with Data Assets, the Task SDK, a rewritten React UI and an Edge Executor. The upgrade guide lists the changes that affect existing code.
| Area | Airflow 3 behaviour | Action for teams |
|---|---|---|
| Task access to the database | Task code can no longer import Airflow database sessions or models; state and XCom go through the Task Execution API | Migrate operators that use database sessions directly |
| Task SDK | A stable interface for accessing Airflow resources; Dataset moves to airflow.sdk.Asset | Update imports; old paths show deprecation warnings |
| Web server | The web server is now an API server, started with airflow api-server | Update deployment scripts |
| Dag processor | Must be started separately with airflow dag-processor, even locally | Add it to every environment |
| Removed features | SubDAGs (use TaskGroups and Assets), Sequential Executor (use LocalExecutor), SLAs (use Deadline Alerts) | Plan replacements before upgrading |
| Scheduling defaults | catchup_by_default is now False | Set catchup explicitly where you rely on it |
| Standard operators | BashOperator and PythonOperator moved to apache-airflow-providers-standard | Install the provider |
| REST API | /api/v1 replaced by FastAPI-based /api/v2 | Update API clients |
| Hybrid executors | CeleryKubernetesExecutor and LocalKubernetesExecutor are replaced by multiple executor configuration | Review executor settings |
What are the benefits of Apache Airflow?
| Benefit | What it means in practice |
|---|---|
| Workflows as code | Dags are Python, so teams can use code review, testing and version control; Jinja templating supports parameterised tasks |
| Visibility | The UI shows runs and logs, and supports manual triggers, backfills and rerunning failed tasks |
| Extensibility | Operators, provider packages and the public interface let teams add systems and execution logic |
| Scale range | The docs say Airflow can run as a single process on a laptop or as a distributed system for large workloads |
| Open source | The project is open source; your team still runs and operates the deployment, so plan for infrastructure and on-call |
How do you install Apache Airflow?
According to the Airflow documentation, Airflow 3.4 supports Python 3.11 to 3.14, PostgreSQL 14 to 18 and MySQL 8.0 and 8.4. SQLite is for local development only: the prerequisites page says not to use it in production. The quick start installs Airflow into a virtual environment with a constraints file, which pins each dependency to the version the release was tested with.
python3 -m venv .venv
source .venv/bin/activate
pip install --upgrade pip

AIRFLOW_VERSION=3.4.0
PYTHON_VERSION="$(python -c 'import sys; print(f"{sys.version_info.major}.{sys.version_info.minor}")')"
CONSTRAINT_URL="https://raw.githubusercontent.com/apache/airflow/constraints-${AIRFLOW_VERSION}/constraints-${PYTHON_VERSION}.txt"
pip install "apache-airflow==${AIRFLOW_VERSION}" --constraint "${CONSTRAINT_URL}"

airflow standalone
airflow standalone starts the API server, scheduler, Dag processor and triggerer on SQLite and is for development only. For production, follow the production deployment guide, use PostgreSQL or MySQL, and choose an executor. Source: Airflow quick start and prerequisites.
Which executor should you choose?
The executor is configured on the scheduler and decides where tasks run. According to the documentation, LocalExecutor is the default and runs tasks inside the scheduler process, so it shares resources with the scheduler. Since Airflow 2.10 you can list several executors and set the first as the default.
| Executor type | Examples | Trade-off (per the Airflow docs) |
|---|---|---|
| Local | LocalExecutor | Fast and simple to set up; shares resources with the scheduler |
| Queued or batch | CeleryExecutor, EdgeExecutor | Workers pull tasks from a central queue; persistent workers can compete for resources |
| Containerised | KubernetesExecutor, EcsExecutor | Each task is isolated in its own container or pod; no worker fleet to manage, but higher startup latency |
Source: Airflow executors.
What are the best practices for Apache Airflow?
| Area | Practice (per the Airflow best practices page) |
|---|---|
| Dag parsing | Keep top-level code to what is needed to create operators and set dependencies; move database access, heavy computation and network calls into task callables |
| Idempotency | Treat tasks like database transactions; use upserts instead of plain inserts; read a specific partition such as one keyed on data_interval_start rather than the latest data |
| Data between tasks | Use XCom for small messages; write larger data to remote storage and pass the path |
| Variables | Avoid Variable.get() in top-level code; use Jinja templates or call it inside the task |
| Secrets | Store credentials as Connections, and use a secrets backend for sensitive variables |
| Testing | Run a loader test, assert no import_errors in DagBag, unit test operators, and parameterise Dags per environment |
| Dependency isolation | Choose between PythonVirtualenvOperator, ExternalPythonOperator and container-based operators based on overhead and isolation needs |
| Housekeeping | Run airflow db clean to purge old data and back up the metadata database before upgrades |
Source: Airflow best practices.
What should governance, security and cost cover?
Orchestrators touch many systems, so treat them as part of your control plane. The points below come from the Airflow documentation; confirm details for your version before you rely on them.
| Concern | Control | Source |
|---|---|---|
| Credentials | Connections and a secrets backend instead of passwords in task code | Best practices page |
| Isolation | Airflow 3 tasks report state through the API server, with no direct metadata database access | Upgrade guide |
| Change control | Dags are code in version control; the Dag processor reads them from a Dag bundle | Architecture overview |
| Reliability | Idempotent tasks so retries do not create duplicates | Best practices page |
| Run cost | Cost comes from the infrastructure you run: scheduler, API server, Dag processor, workers and database. Container-per-task executors trade startup latency for isolation | Executor page |
| Upgrade risk | Back up the metadata database before upgrades; plan for removed features | Best practices and upgrade guide |
Governed AI workflows need more than scheduling: they need the context, policy and decision trace behind each automated step. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. Teams that want to query pipeline outputs in plain language can look at AgentAnalyst.
When is Apache Airflow not the right choice?
The documentation positions Airflow as best suited to batch workflows with a clear start and end that run on a schedule. If you need continuous, low-latency stream processing, use a streaming engine and let Airflow coordinate the batch work around it. If your estate is mostly Azure data movement, compare options in Airflow vs Azure Data Factory. For small teams, the cost of running the scheduler, database and workers can outweigh the benefit of a code-first orchestrator, so weigh managed offerings too.
How should you adopt Apache Airflow?
- Start on Airflow 3 and check the upgrade guide for any existing Airflow 2 code.
- Pick one batch pipeline with a clear owner and a clear start and end.
- Set up PostgreSQL or MySQL, the Dag processor and an executor that matches your isolation needs.
- Write idempotent tasks, store credentials as Connections and keep Dags in version control.
- Add tests: loader test,
DagBagimport check and operator unit tests. - Set alerting and a runbook for failed runs, then add further pipelines.
To map one decision your pipelines and agents make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Apache Airflow FAQ
What is Apache Airflow used for?
Apache Airflow is used to develop, schedule and monitor workflows written in Python as Dags. According to its documentation, it handles scheduled or event-triggered batch pipelines, machine learning training and AI or LLM workloads.
Is Apache Airflow a streaming tool?
No. The Airflow documentation positions it as best suited to batch workflows with a clear start and end that run on a schedule. Use a streaming engine for continuous processing.
What changed in Apache Airflow 3?
Airflow 3 adds the Task SDK and Task Execution API, an API server, a standalone Dag processor and Assets. Task code can no longer access the database directly, and SubDAGs, the Sequential Executor and SLAs are removed. See the upgrade guide for details.
Which Python and database versions does Airflow 3.4 support?
According to the prerequisites page, Python 3.11 to 3.14, PostgreSQL 14 to 18 and MySQL 8.0 and 8.4. SQLite is for development only.
Which Airflow executor should I use?
LocalExecutor is the default and runs tasks inside the scheduler. CeleryExecutor uses persistent workers pulling from a queue, and KubernetesExecutor runs each task in its own pod with more isolation but higher startup latency.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE