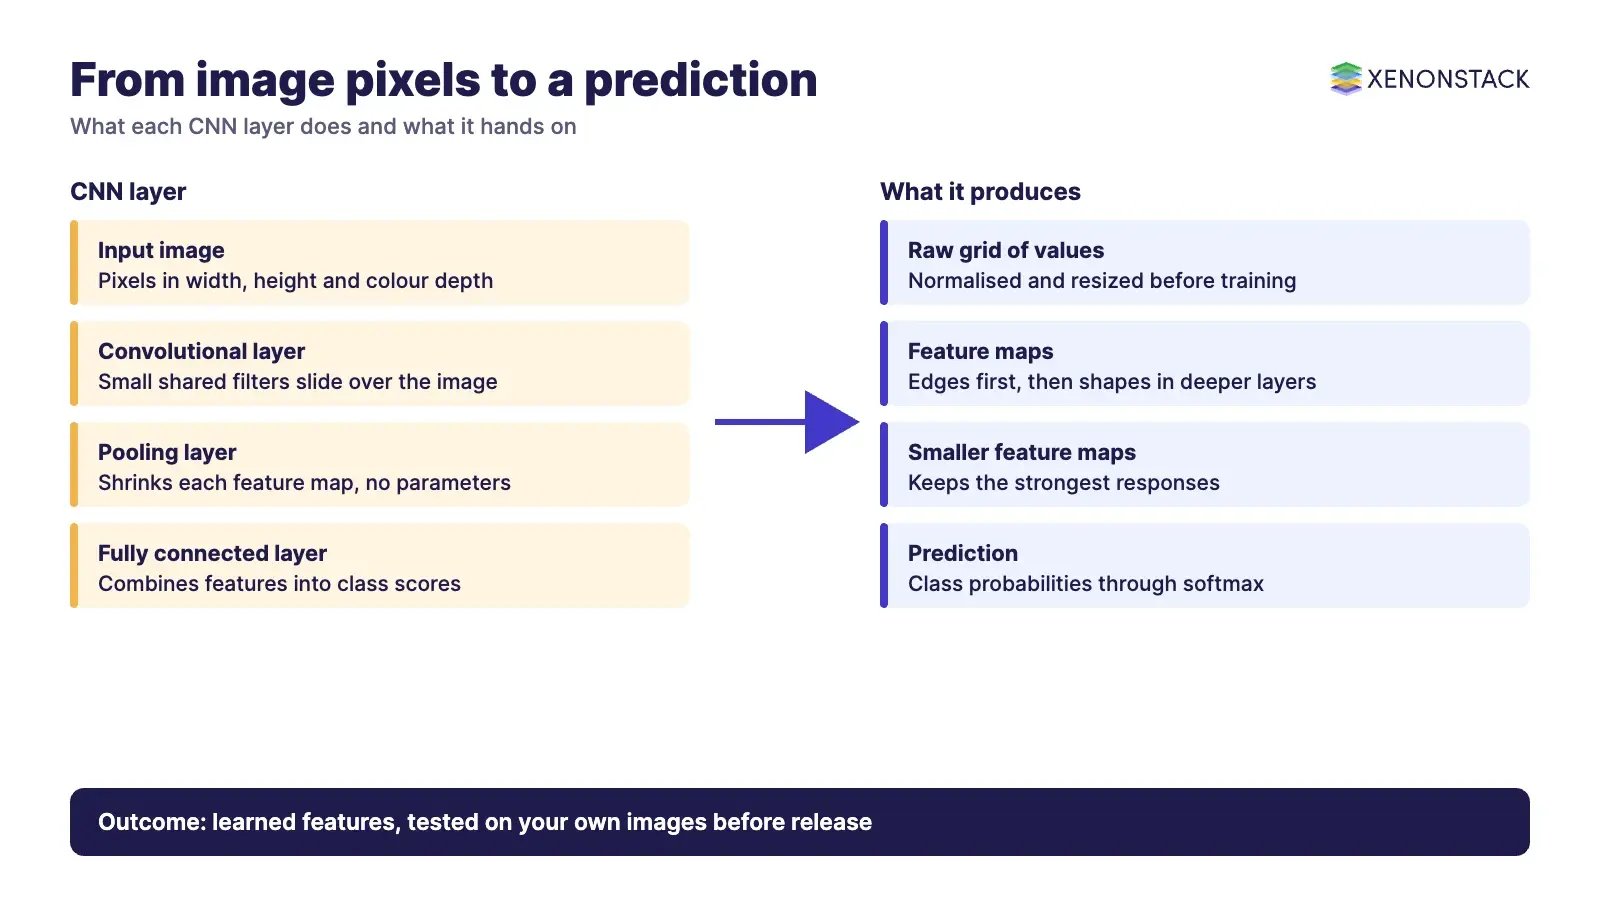
A convolutional neural network (CNN) is a neural network that learns to read grid-like data, mostly images, by sliding small filters across the input and stacking the results layer by layer. Early layers pick up edges and colours, later layers combine them into shapes and objects, and a final layer turns the features into a prediction. IBM's overview describes the same three building blocks: convolutional, pooling and fully connected layers (IBM).
This guide is for CTOs, chief data officers and architects who need to know what a CNN does, which architecture to start from, what it costs to run and where it is heading. It covers the layers, the architectures from LeNet to MobileNet, the build sequence, uses, a 3 to 5 year outlook and the governance questions to settle before production. For the newer alternative, see our Vision Transformer versus CNN decision guide.
Key takeaways
- A CNN reuses one small filter across the whole image, which keeps the parameter count low. In the Stanford CS231n notes, the first AlexNet layer needs 34,944 parameters with sharing, against about 105.7 million without it.
- Start from a proven architecture such as ResNet or MobileNet and fine-tune it, rather than designing layers from scratch.
- CNNs now share the field with Vision Transformers. Choose by data volume, latency and the device the model must run on.
How does a CNN work layer by layer?
The Stanford CS231n notes set out the mechanics. Each filter is small in width and height but spans the full depth of its input; a first-layer filter on an RGB image might be 5x5x3. Sliding it over the image produces one activation map, and the maps from all filters are stacked into the layer's output.
| Layer | What it does | Design choices |
|---|---|---|
| Convolutional | Applies small filters to local regions and builds feature maps. Neurons in one depth slice share weights, which cuts parameters sharply | Number and size of filters, stride, padding. Output width is (W - F + 2P) / S + 1 |
| Activation (ReLU) | Adds non-linearity after each convolution so stacked layers can learn more than a single linear filter | Usually ReLU in the CS231n pattern CONV, RELU |
| Pooling | Reduces the width and height of each feature map without parameters. Max pooling with a 2x2 window and stride 2 discards 75% of activations | Max or average pooling, window size, stride |
| Fully connected | Combines the extracted features and produces class scores, typically through softmax | Number of layers and units; some modern designs replace these with average pooling |
A common pattern in those notes is INPUT, then several CONV and RELU layers with an occasional POOL, then one or two fully connected layers. Stacking small 3x3 filters is generally preferred to one large filter: three stacked 3x3 layers cover a 7x7 receptive field with fewer parameters and extra non-linearity.
Before CNNs, image models relied on hand-built features. A CNN learns the filters from labelled data, which is why it needs a representative training set. For the full pipeline around the model, see our guide to the computer vision workflow, and for how CNNs relate to other model types, deep learning versus machine learning versus neural networks.
Which CNN architecture should you start from?
| Architecture | What the source says | When it fits |
|---|---|---|
| LeNet | Yann LeCun's network for handwritten and machine-printed character recognition; his page lists a 1998 Proceedings of the IEEE paper on gradient-based learning for document recognition (LeCun) | Teaching and small digit or character tasks |
| AlexNet | Krizhevsky, Sutskever and Hinton (NIPS 2012): five convolutional layers, 60 million parameters, 500,000 neurons, GPU training; 18.9% top-5 error on the LSVRC-2010 test data (NeurIPS). In ILSVRC 2012 it reached about 16% top-5 error against 26% for the runner-up (CS231n) | Historical reference; rarely the best choice today |
| GoogLeNet (Inception) | 22-layer network from Szegedy et al. that uses computing resources more efficiently, with a design that lets depth and width grow without extra cost; ILSVRC 2014 (arXiv). See our Inception guide | Accuracy per unit of compute matters |
| VGGNet | Simonyan and Zisserman: depth of 16 to 19 weight layers with very small 3x3 filters; second in ILSVRC 2014 classification, first in localisation (arXiv). CS231n notes that it is expensive to evaluate, with about 140 million parameters | A simple, uniform backbone; heavy to run |
| ResNet | He et al.: residual networks up to 152 layers, described as 8 times deeper than VGG nets with lower complexity; the ensemble won ILSVRC 2015 classification with 3.57% error on the test set (arXiv) | A default backbone for classification and detection when accuracy is the priority |
| MobileNets | Howard et al. (2017): small, low-latency CNNs built on depthwise separable convolutions, with two hyperparameters that trade latency against accuracy (arXiv) | Phones, embedded and edge devices |
ZFNet, the ILSVRC 2013 winner, improved on AlexNet by adjusting the first-layer filter size and stride, according to the CS231n notes. For a decision on whether a transformer is a better fit than any of these, use the ViT versus CNN guide.
How do you build and deploy a CNN?
- Prepare the data. Collect labelled images that match the conditions the model will see in production, then normalise and resize them.
- Choose the architecture. Start from a pretrained backbone from the table above and fine-tune it on your data.
- Train. A loss function measures the error between predicted and actual labels, and an optimiser such as Adam (Kingma and Ba) or stochastic gradient descent updates the weights.
- Evaluate on held-out data. Report accuracy, precision, recall and F1 on images the model has not seen, and report them per class and per site.
- Deploy and monitor. Serve the model in the cloud or on the device, and watch for drift when lighting, cameras or products change. See our guide to machine learning model deployment testing.
Where are CNNs used in the enterprise?
IBM lists image classification and object recognition as the main uses, with examples in healthcare (helping radiologists identify tumours in medical images), automotive (lane line detection), retail (visual search) and marketing (suggesting who appears in social media photos). Common enterprise tasks fall into four groups.
| Task | What the CNN does | What to check before production |
|---|---|---|
| Image classification | Assigns one label to an image | Accuracy on your own images, not only a public benchmark |
| Object detection | Finds and locates objects in images or video | Latency and the cost of false alarms and misses |
| Segmentation | Labels each region or pixel with a class | Quality of the labelled masks, which are costly to create |
| Video analytics | Applies image models frame by frame, often with extra temporal modelling | Privacy, retention and who may view the footage |
Medical and safety uses need regulatory and clinical review, and a CNN output should support a person's decision rather than replace it. Where the model runs on a camera or gateway, see computer vision on the edge and Arm processors for mobile AI vision.
What will change in CNNs over the next 3 to 5 years?
The sources below show direction rather than a forecast. The outlook column is our judgement, labelled as such.
| Trend | Evidence (date and source) | Outlook for enterprise teams (our judgement) |
|---|---|---|
| Transformers join CNNs | Dosovitskiy et al. (October 2020) show a pure transformer on image patches matching or beating leading CNNs on ImageNet and CIFAR-100 when pretrained on large datasets (arXiv) | Expect mixed estates: transformers where data and compute are plentiful, CNNs where latency and device limits dominate |
| CNNs modernised | Liu et al. (January 2022) modernise a ResNet into ConvNeXt, a pure ConvNet reaching 87.8% ImageNet top-1 accuracy and competitive with transformers (arXiv) | CNN designs keep improving; the choice is empirical, so benchmark both on your data |
| Efficient models for devices | Qin et al. (April 2024) present MobileNetV4, which mixes convolution and attention blocks; MNv4-Hybrid-Large reaches 87% ImageNet-1K accuracy at 3.8 ms on a Pixel 8 EdgeTPU (arXiv) | On-device inference becomes the default for many camera workloads; plan device fleet management |
| Regulation | The EU AI Act timeline lists 2 August 2026 for most rules, including transparency obligations, and 2 December 2027 and 2 August 2028 for high-risk rules, marked as amended by the Digital Omnibus on AI (AI Act Service Desk) | Classify each vision use case by risk now and keep model documentation; confirm dates on the official page |
What governance and cost questions apply to CNNs?
- Data: training images may contain faces, premises or patient data. Settle consent, retention and access before collecting them.
- Compute: deeper networks cost more to train and run. VGGNet is expensive to evaluate, and MobileNets exist to reduce that cost on devices.
- Accuracy transfer: a model trained on one set of images can fail on another. Test on your own production images and report results per site.
- Traceability: record which model version made which prediction, on which input, and who confirmed it. This is our recommendation, not a published standard.
For the traceability point, ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need. For models that run at the edge, NexaStack is an agentic operating platform for physical AI that runs across on-premises, cloud and hybrid environments.
To map one vision decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions about convolutional neural networks
What is a convolutional neural network in simple terms?
A CNN is a neural network that slides small filters across an image to detect features, from edges in early layers to whole shapes in later ones, then uses fully connected layers to classify the result (IBM).
What are the main layers of a CNN?
Convolutional layers extract features, pooling layers reduce the size of the feature maps, and fully connected layers combine the features into class scores. Activation functions such as ReLU sit between them (IBM, Stanford CS231n).
Which CNN architecture should we start with?
Start from a pretrained ResNet when accuracy is the priority and from a MobileNet when the model must run on a phone or edge device, then fine-tune on your own labelled images.
Are CNNs being replaced by Vision Transformers?
Not outright. A 2020 paper showed a transformer matching or beating leading CNNs when pretrained on large datasets, and a 2022 paper showed a modernised CNN, ConvNeXt, competing with transformers. The choice depends on data, latency and hardware.
What should a CNN project settle before production?
Data consent and retention, accuracy on your own images per site, a human confirmation step for high-stakes decisions, model version traceability and the risk class of the use case under rules such as the EU AI Act.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE