Key takeaway
- Synthetic patient data with agentic AI on Databricks: how agents generate, validate and release it under governance, which methods fit, and its limits.
Synthetic patient data is artificial patient-level data that keeps the statistical shape of real records without describing real people. It lets healthcare and life sciences teams build, test and share without waiting for access to protected health information. It is not automatically private, though: how it was made, and from what, decides the risk.
Agentic AI on Databricks adds a controlled workflow around generation: agents prepare inputs, run a generator, check fidelity and privacy, and register the result, while Unity Catalog and human reviewers hold the gates. This guide is for CIOs, CDOs, CISOs and data platform leads deciding where that pattern fits. It builds on our guides to agentic AI in healthcare, AI agents for the Databricks Lakehouse and synthetic data generation with agentic AI.
What is synthetic patient data and why does it matter to healthcare enterprises?
Real patient data is sensitive, spread across systems and slow to release. Under the US HIPAA Privacy Rule, data counts as de-identified only through one of two routes: Expert Determination, where a qualified expert finds the risk of identification very small, or Safe Harbor, where 18 categories of identifiers are removed (HHS guidance on de-identification). Both routes take time and still leave teams with a thin copy of reality.
Synthetic data offers a third option for many non-production uses: model training, software testing, demos, vendor evaluation and early research design. It also supports downstream work such as predictive analytics in patient care, where teams need realistic records before they are cleared to touch live ones.
How do agents generate synthetic patient data on Databricks?
A pipeline has a few distinct stages. Agents are useful for the coordination between them, not for replacing the generator or the reviewer. The table shows the pattern we use and where a person stays in the loop.
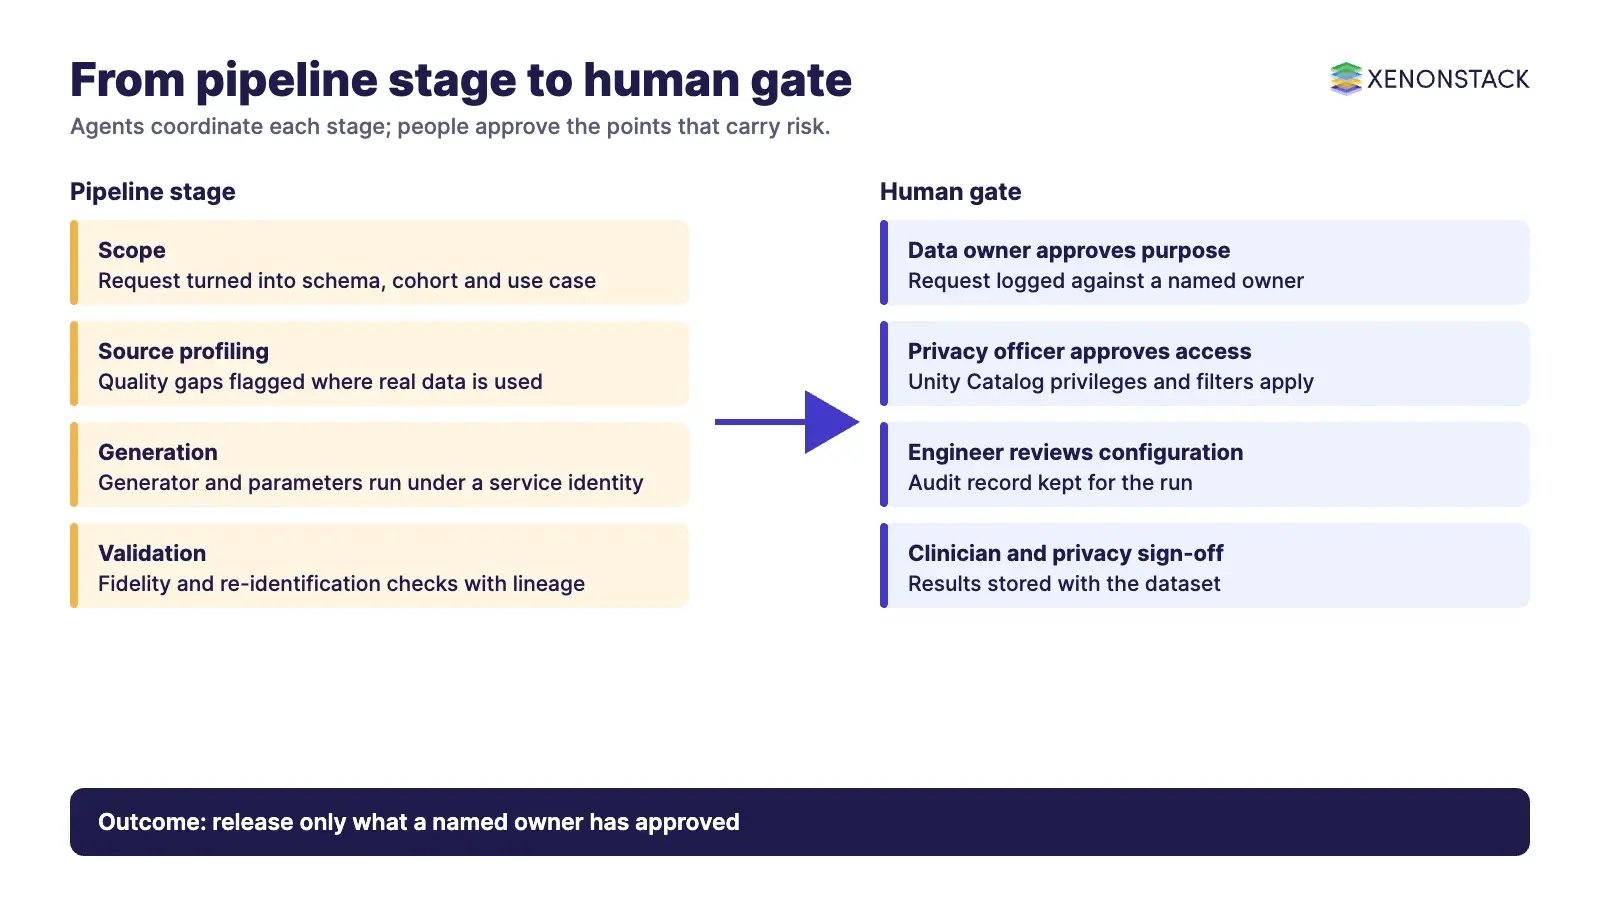
| Stage | What the agent does | Control on Databricks | Human gate |
|---|---|---|---|
| Scope | Turns a request into a schema, cohort definition and use case | Request logged against a named owner | Data owner approves purpose |
| Source profiling | Profiles source tables and flags quality gaps, only where real data is used | Unity Catalog privileges, row and column filters | Privacy officer approves access |
| Generation | Selects and runs a generator and parameters | Jobs run under a service identity, with an audit record | Engineer reviews configuration |
| Validation | Compares distributions, key integrity and clinical rules against benchmarks; runs re-identification checks | Results stored with the dataset and lineage | Clinician and privacy reviewer sign off |
| Release | Registers the dataset, tags its provenance and grants access | Catalog tags, privileges and audit log | Owner approves each consumer |
Databricks describes Unity Catalog as the place to manage access with privileges, row and column filters, automatic lineage and a record of data access and system activity in an audit log (Databricks documentation). Databricks also says that agents built with Agent Bricks inherit the same identity, security and access permissions as human users, which it presents as a way to keep AI work auditable in PHI-sensitive environments (Databricks healthcare and life sciences page). For a synthetic pipeline this means the agent never holds broader access than the person who commissioned the work.
Which generation method fits which need?
There is no single method. Choose by how much realism you need and whether real patient records feed the generator.
| Method | When it fits | Current status and caution |
|---|---|---|
| Simulated patients with Synthea | Interoperability tests, demos, training data where no real records should be touched | Open source from MITRE; produces patient histories in HL7 FHIR, C-CDA and CSV. Described as "realistic but not real" (Synthea). Rule-based, so it will not reproduce the quirks of your own population. |
| Schema-driven generation with dbldatagen | Load testing, pipeline tests, repeatable test fixtures at scale | A Databricks Labs Python library for Spark with consistent primary and foreign keys; Labs projects are provided as-is without formal support (dbldatagen). Generates structure, not clinical truth. |
| Models trained on real records | Analytics and ML where distributions must match your population | Highest realism and highest privacy risk. The source data stays under full governance, and release needs privacy testing and approval. |
The first two rows never see real patients, which makes them the quickest route to value. The third is where most governance effort belongs.
Does synthetic data remove HIPAA and GDPR obligations?
Not by itself. NIST SP 800-188 lists generating synthetic data with models among de-identification techniques, next to others such as query interfaces and enclaves, so it is treated as a technique to be assessed, not as a free pass (NIST SP 800-188). Researchers have also found that synthetic data generation does not give a better privacy and utility trade-off than traditional anonymisation, and that the outcome is hard to predict (Stadler, Oprisanu and Troncoso).
In practice, treat any dataset generated from real records as sensitive until a documented privacy review says otherwise. Whether a particular dataset is anonymous under HIPAA or GDPR is a legal and expert determination for your own counsel and privacy officer, not something a tool can certify.
How should you govern a synthetic data pipeline?
- Provenance: record the source, generator, version, parameters and reviewer for every dataset, and tag it as synthetic in the catalogue.
- Least privilege: agents run under service identities with only the access the task needs, and source data stays in its own governed schema.
- Privacy testing: test for re-identification and record linkage before release, and keep the results with the dataset.
- Fidelity checks: compare against agreed benchmarks, including clinical plausibility reviewed by a clinician.
- Approval trail: keep a decision record of who approved each release and for which consumer. Our guide to data governance covers the operating model.
For teams running several agents, ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need. ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
Where do enterprises use synthetic patient data?
| Use case | How synthetic data helps | Watch for |
|---|---|---|
| Clinical research design | Prototype cohorts and analysis plans before real data access is approved | Do not draw clinical conclusions from synthetic records |
| AI diagnostics and ML development | Build and test pipelines and features when real data is limited | Validate final models on governed real data |
| Population health analytics | Test dashboards and risk models on realistic structure | Rare conditions are often under-represented |
| Medical device and software testing | Exercise systems with varied patient scenarios and edge cases | Coverage depends on the scenarios you specify |
| Compliance and system testing | Test EHR integrations and audit workflows without exposing real records | Confirm the test data meets your security policy |
What are the trade-offs, and when should you not use synthetic data?
Do not use synthetic data as the only evidence for a clinical, safety or regulatory decision. It reflects the generator and its inputs, so errors and gaps carry through. Rare diseases and small subgroups are the hardest to reproduce faithfully.
There is a second risk when generated data is reused to train further generators. Research shows that training recursively on generated data makes models lose the tails of the original distribution (Shumailov et al.), while accumulating synthetic data alongside the real data avoids that collapse (Gerstgrasser et al.). Keep real, governed data in the loop for validation and refresh.
What is a sensible adoption sequence?
- Start without real records. Use Synthea or dbldatagen for test environments and demos.
- Define governance first. Agree provenance tags, approvers and release rules in Unity Catalog.
- Add agents for coordination. Automate scoping, runs and validation reports, with human gates kept.
- Introduce models trained on real data last. Only after privacy testing and approval are in place.
- Review on a schedule. Re-test fidelity and privacy when sources or generators change.
To map one synthetic data release decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is synthetic patient data the same as de-identified data?
No. HIPAA recognises de-identification through Expert Determination or Safe Harbor. Synthetic data is a different technique, and NIST lists it among de-identification techniques that need assessment.
Is synthetic patient data always private?
No. Research has found that synthetic data generation gives no better privacy and utility trade-off than traditional anonymisation, so test each dataset before release.
What can I use to generate it on Databricks?
Teams commonly use dbldatagen, a Databricks Labs library for schema-driven data on Spark, or Synthea, an open-source patient simulator from MITRE, and add governance through Unity Catalog.
What do agents add to the process?
They coordinate scoping, generation runs, validation and release records under governed identities, with humans approving the key gates.
When should I avoid synthetic data?
Avoid it as the sole evidence for clinical, safety or regulatory decisions, and be careful with rare conditions and with repeatedly regenerating from generated data.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE