Key takeaway
- Performance tracing shows where a request spends its time. Learn traces, spans, W3C context propagation, sampling and the Go execution tracer.
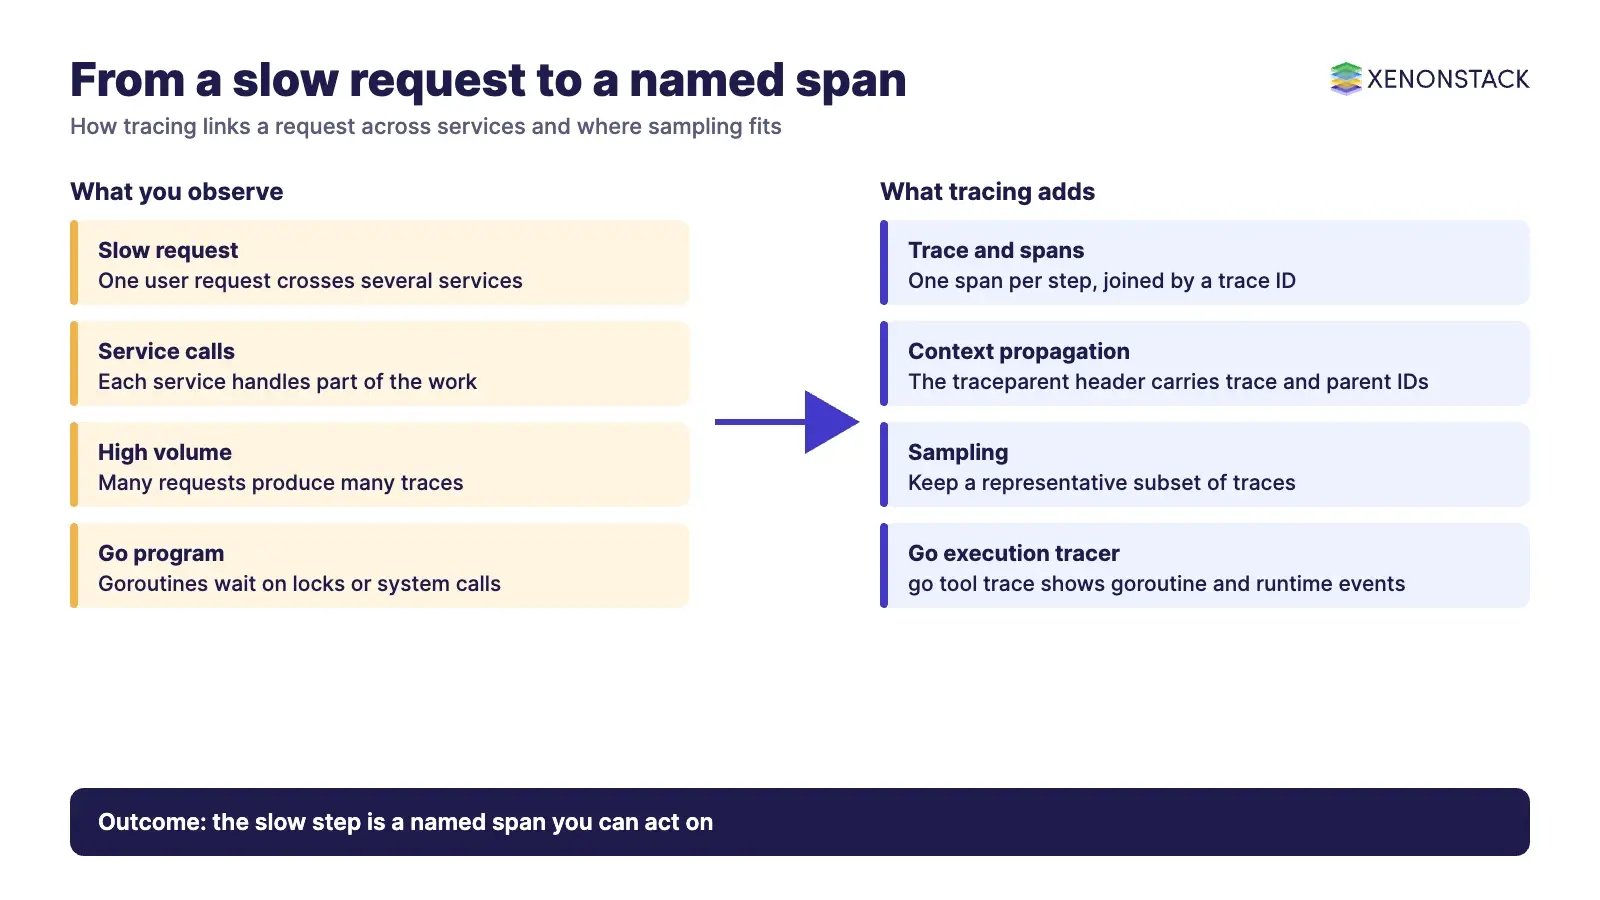
Performance tracing records the path of one request or one program run as a set of timed steps, so you can see where the time went. In a distributed system, a trace follows a request across services and is built from spans, each span being one unit of work with a start time, an end time and a parent. In a single Go program, the runtime execution tracer plays a similar role for goroutines, garbage collection and system calls.
Tracing answers a different question from load testing or tuning. Performance testing tells you whether a system meets its targets under load, and performance tuning changes the system to meet them. Tracing tells you which step of a slow request to look at first. This guide uses the OpenTelemetry traces documentation, the W3C Trace Context specification and the Go runtime/trace package as its sources.
What is performance tracing, and how is it different from metrics and logs?
According to OpenTelemetry, traces give the big picture of what happens when a request is made to an application. A trace is a collection of spans that share a trace ID and are linked by parent IDs, and the spans can come from different processes, services or data centres. Metrics tell you that something is slow, and logs tell you what a component said. A trace tells you which step in the chain of calls took the time.
How does a trace work?
A span is one unit of work in a trace. OpenTelemetry shows a span carrying a name, a trace ID, a span ID, a parent ID, a start time, an end time, attributes and events. A span with no parent is the root span, and it marks the start and end of the whole operation. The table below sets out the parts you meet when you instrument a service.
| Part | What it does | Where it is defined |
|---|---|---|
| Trace | Groups all spans that belong to one request | OpenTelemetry traces concept page |
| Span | Records one unit of work with start, end, parent, attributes and events | OpenTelemetry traces concept page |
| Tracer provider | A factory for tracers, usually initialised once per application, together with the resource and exporter | OpenTelemetry traces concept page |
| Tracer | Creates spans for an operation, such as a request handled by a service | OpenTelemetry traces concept page |
| Exporter | Sends traces to a consumer: standard output while developing, the OpenTelemetry Collector or a vendor backend | OpenTelemetry traces concept page |
How does a trace follow a request across services?
The mechanism is context propagation. OpenTelemetry describes it this way: service A sends its trace ID and span ID, and service B uses them to create a span in the same trace, with service A's span as the parent. The sending side serialises the context and the receiving side reads it back. Instrumentation libraries usually do this for you.
The default propagator uses the headers set out in the W3C Trace Context specification. The W3C Recommendation of 23 November 2021 defines a traceparent header with four dash-separated fields: a two-character version, a 32-character trace ID, a 16-character parent ID and two characters of trace flags. Its example is 00-4bf92f3577b34da6a3ce929d0e0e4736-00f067aa0ba902b7-01, where the last field marks the request as sampled by the caller. A companion tracestate header carries vendor-specific information as a list of key and value pairs, with a maximum of 32 entries.
Should you sample traces?
Sampling means keeping a representative subset of traces. OpenTelemetry separates the two states: a trace is sampled when it is processed and exported, and not sampled when it is not. Head sampling decides as early as possible and does not inspect the whole trace. Its common form decides from the trace ID and a chosen percentage. Tail sampling decides later, with the whole trace in view; confirm its current behaviour and trade-offs on the OpenTelemetry sampling page before you design around it.
| Situation | Sampling guidance from OpenTelemetry |
|---|---|
| Very high trace volume, for example 1000 or more traces a second | Consider sampling |
| Mostly healthy traffic with common failure signals such as errors or high latency | Consider sampling |
| Dropped data can go to low-cost storage | Consider sampling |
| Low data volume, or you only use the data in aggregate | Avoid sampling |
| Regulations prohibit dropping data | Avoid sampling |
OpenTelemetry also lists three costs of sampling: the compute needed to sample well, the engineering effort to maintain sampling logic as systems grow, and the risk of missing critical information if the sampling is poor.
How do you trace a Go program?
The Go execution tracer is the program-level form of tracing. According to the runtime/trace documentation, it captures goroutine creation, blocking and unblocking, system call events, garbage collection events, heap size changes and processor start and stop. Most events carry a nanosecond timestamp and a stack trace.
You can turn it on in three ways:
- For tests and benchmarks, run
go test -trace=trace.outto write a trace file. - For a standalone program, call
trace.Start(w)and latertrace.Stop()from the runtime/trace package. - For a live service, import
net/http/pprof, which installs a handler at/debug/pprof/tracefor downloading a live trace.
Open the resulting file with go tool trace trace.out. The tool visualises each goroutine's execution over the recorded period, which helps you spot goroutines that wait on locks, channels or system calls, and work that is poorly spread across processors.
The same package lets you annotate your own code. A task, created with NewTask, marks a logical operation such as an HTTP request that can span several goroutines, and the trace tool reports latency from creation to End by task type. A region, created with WithRegion or StartRegion, marks a time interval inside one goroutine. Log adds a timestamped event.
On cost, the Go blog post on execution traces of 14 March 2024 says that before Go 1.21 tracing overhead was between 10 and 20 per cent CPU, and that it fell to 1 to 2 per cent for many applications. The same post describes a flight recorder, in the golang.org/x/exp/trace package, as an experiment that keeps recent trace data so a program can save a snapshot when something interesting happens. Check go.dev for its current status before you depend on it.
Which tracing approach fits which problem?
| Problem | Approach | What you get | Status and source |
|---|---|---|---|
| A request is slow and crosses several services | Distributed tracing with OpenTelemetry and W3C Trace Context | One trace with a span per step, joined by propagated context | W3C Recommendation, 23 November 2021; OpenTelemetry docs |
| A Go service uses CPU or waits unevenly | Go execution tracer and go tool trace | Goroutine, scheduler, garbage collection and system call events | Part of the Go standard library, runtime/trace |
| You need to name a business step inside Go code | Tasks, regions and logs in runtime/trace | Latency by task type and timed regions | runtime/trace documentation |
| Trace volume or storage cost is too high | Sampling | A representative subset of traces | OpenTelemetry sampling page |
What should you watch for on governance, security and cost?
- Span attributes and events are stored data. Decide what may appear in them, and keep personal data and secrets out.
- Propagated headers cross service boundaries, so check what each downstream service does with them.
- Sampling lowers cost but can drop the one trace you needed. Decide the rule before an incident, not during one.
- Tracing overhead is not zero. Measure it on your own workload before enabling it everywhere.
How should you adopt performance tracing?
- Pick one slow, important request path and trace only that.
- Instrument the entry service and every service it calls, so context propagates end to end.
- Send traces to a Collector or a backend your team already operates.
- Add custom spans, or Go tasks and regions, for the steps you cannot see.
- Set a sampling rule once volume grows, then review it after each incident.
- Link traces to your load tests, so a regression in performance testing points to a span, and feed the findings into performance engineering work.
When is tracing not the right tool?
Tracing is a poor fit when you only need an aggregate, such as error rate or p95 latency over a week, because metrics answer that more cheaply. It also adds little to a single-process job whose cost is plain CPU time, where a profiler is the better first step. For wider context, see performance monitoring, automated performance testing and system testing.
Teams that run AI agents in production need the same discipline for what an agent did and why. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
To map one decision your agents make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is performance tracing?
Performance tracing records the timed steps of a request or program run so you can see where the time went. In distributed systems the steps are spans grouped into a trace; in Go, the execution tracer records goroutine, scheduler, garbage collection and system call events.
What is the difference between a trace and a span?
A span is one unit of work with a name, start and end time, parent and attributes. A trace is the collection of spans that share a trace ID, linked by parent IDs. A span with no parent is the root span.
How does context propagation work?
The sending service serialises its trace ID and span ID into headers, and the receiving service reads them and creates a span in the same trace with the sender's span as parent. The default propagator uses the W3C Trace Context traceparent header.
Do I need to sample traces?
Consider sampling when trace volume is very high, traffic is mostly healthy or dropped data can go to cheap storage. OpenTelemetry advises avoiding it when data volume is low, when you only use data in aggregate or when regulations prohibit dropping data.
How do I trace a Go program?
Run go test -trace=trace.out for tests and benchmarks, call trace.Start and trace.Stop in a program, or import net/http/pprof for a live trace at /debug/pprof/trace. Then open the file with go tool trace.
Conclusion
Performance tracing turns a vague report that a request is slow into a named span you can fix. Use OpenTelemetry and W3C Trace Context to follow requests across services, use the Go execution tracer to look inside a Go program, and set a sampling rule before volume forces one on you.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE