Key takeaway
- Big data tools by layer: storage formats, Spark, Flink, Kafka, catalogs and managed platforms, what was retired, and how to choose a stack for AI.
Big data tools and technologies are the software layers that store, move, process, govern and serve data sets too large, too fast or too varied for a single conventional database. Today they are assembled as separate layers, usually sharing data through open file and table formats, rather than bought as one product.
This guide is for data leaders, architects and engineering managers choosing or reviewing a stack. It covers the main tool categories, what has been retired or replaced since the Hadoop era, six criteria for choosing, and how AI agents change the requirements. For the wider design, see our guides to big data architecture and big data platforms.
Which big data tools belong in each layer?
Think in layers, because each layer carries its own cost, skills need and lock-in risk. The table lists the common categories and the open source and managed tools usually found in them. Check each project's own site for its current release and licence before you standardise.
| Layer | Common tools | When the layer matters |
|---|---|---|
| Storage and table formats | Object storage with Apache Iceberg, Delta Lake or Apache Hudi | You want one copy of data that several engines can read and write, with schema changes and history |
| Batch processing | Apache Spark, Apache Hadoop for existing HDFS estates | Large transformations, feature engineering and machine learning preparation |
| Stream processing | Apache Flink | Stateful, low-latency processing of continuous events |
| Interactive SQL | Trino, Presto, DuckDB for single-machine work | Analysts need fast SQL without copying data first |
| Event streaming | Apache Kafka and Kafka-compatible platforms | A durable backbone for events and change data capture |
| Real-time analytics | Apache Druid | Fast queries on fresh event data behind dashboards |
| Orchestration and transformation | Apache Airflow, Dagster, dbt | Scheduling pipelines and modelling data with tests and version control |
| Catalogs and governance | Unity Catalog, Apache Polaris, DataHub, OpenMetadata | Shared access control, lineage and discovery across engines |
| Managed platforms | Google BigQuery, Amazon Redshift, Snowflake, Databricks | You prefer less platform engineering and accept usage-based pricing |
Our engine guides go deeper on Apache Spark architecture, Apache Flink and Apache Druid, and on the managed options Google BigQuery and Amazon Redshift with QuickSight. For getting data in, see our data ingestion tools and architecture guide.
What has changed since the Hadoop era?
Older tool lists are full of projects that have since been retired or replaced, so treat any dependency on them as a roadmap risk.
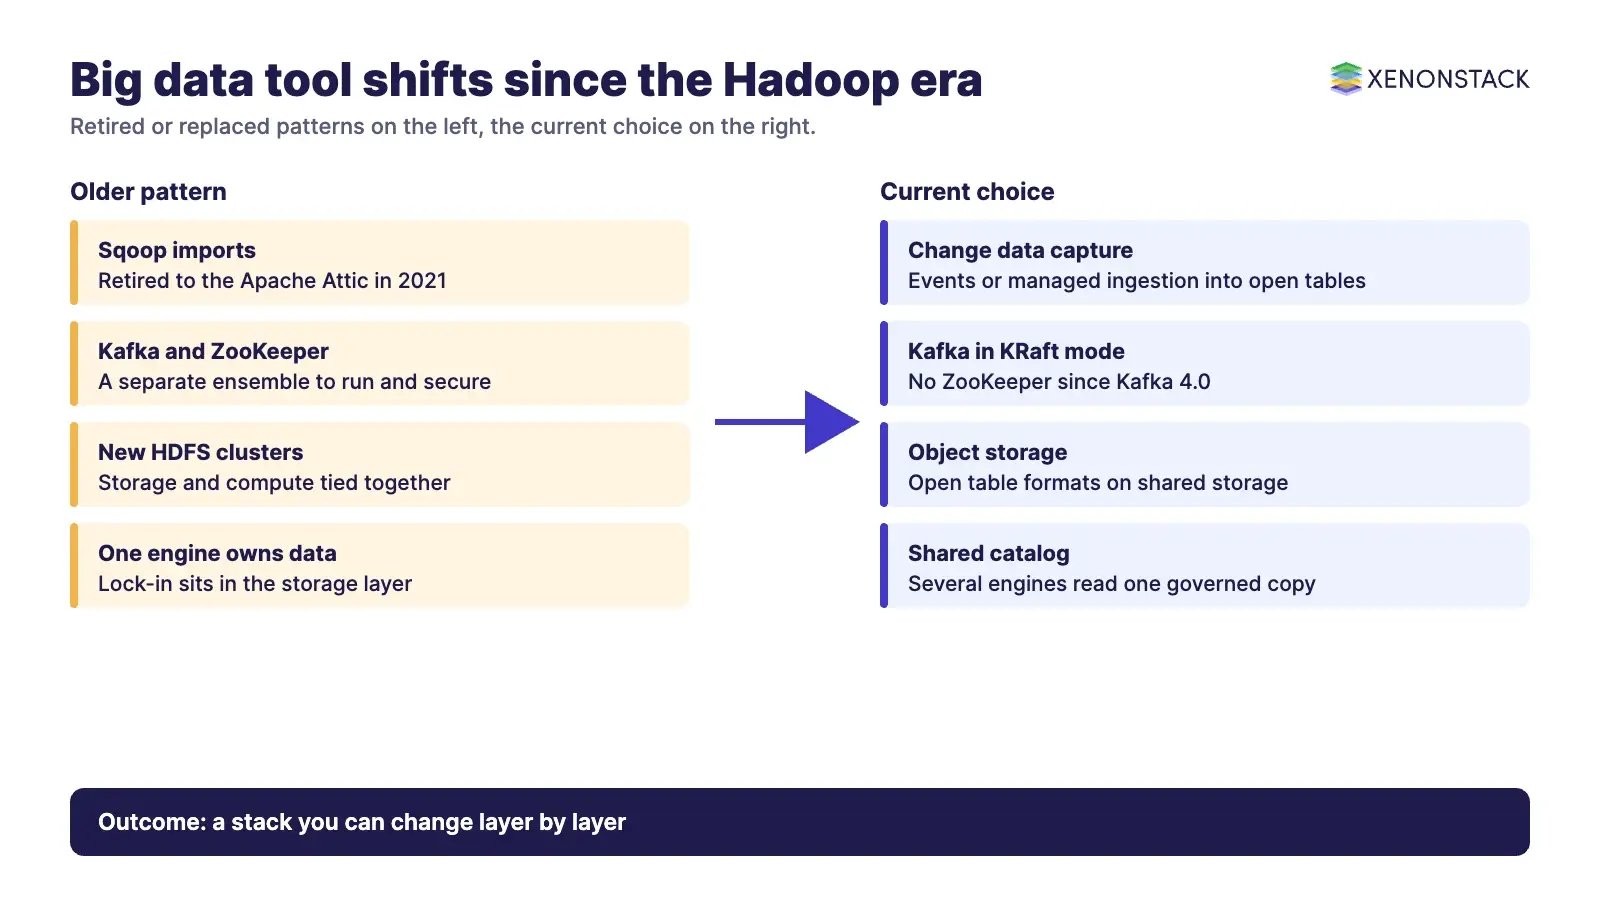
The Apache Software Foundation lists Apache Sqoop in its Attic of retired projects. The Apache Attic page for Sqoop says it was "retired in June 2021" and that "the move to the Attic was completed in July 2021". Sqoop moved data between relational databases and Hadoop, and that need is now usually met by change data capture into an event stream or by managed ingestion that lands data in open table formats.
Streaming changed too. The Apache Kafka 4.0 announcement, dated 18 March 2025, describes the release as "the first major release to operate entirely without Apache ZooKeeper". It says running in KRaft mode by default removes the need for a separate ZooKeeper ensemble. Teams on older clusters need a migration plan before moving to the 4.x line.
| Older pattern | Where teams are heading | Why it matters |
|---|---|---|
| Sqoop for database imports | Change data capture or managed ingestion into open tables | The retired project no longer has an active Apache community |
| Kafka with ZooKeeper | Kafka in KRaft mode | One fewer system to run and secure |
| New HDFS clusters | Object storage with an open table format | Storage and compute can be chosen and replaced separately |
| One engine owns the data | Several engines read one governed copy | Lock-in moves from storage to the catalog |
How should you choose big data tools?
Start from the decisions the business needs to make, not from product names. These six criteria separate a stack that scales from one that is costly to change.
| Criterion | Question to ask | What it points towards |
|---|---|---|
| Scale | Does the working data fit on one large machine? | Single machine: DuckDB or a managed warehouse. Larger: Spark or Trino over open tables |
| Latency | Do decisions need data in seconds, minutes or by tomorrow? | Seconds: Kafka with Flink. Minutes to hours: scheduled Spark or dbt runs |
| Skills | Is the team SQL-first, Python-first or JVM-first? | SQL-first teams gain most from managed warehouses, dbt and Trino |
| Cost | Where does spend concentrate? | Separate storage from compute and count operating effort for self-managed tools |
| Lock-in | Can another engine read your data tomorrow? | Open table formats and catalogs with open APIs |
| Governance | Can you show who accessed what, and where data came from? | Choose the catalog early and enforce access and lineage there |
Governance deserves early attention because every added engine needs coverage. Our data governance guide sets out the controls, and our big data testing strategy guide covers checks at each stage.
What are the trade-offs between managed and open source tools?
- Managed services reduce operating effort, but pricing is usage-based and some features work only inside one vendor's environment.
- Self-managed open source avoids licence fees and gives control, but you carry upgrades, patching and on-call support. Review project health every year.
- Open table formats lower storage lock-in, but the catalog becomes the new point of control.
- Real-time pipelines give fresher decisions at higher cost and complexity. Use them where delay has a clear business cost.
- Fewer tools mean less integration work, because each extra engine needs skills, monitoring and governance.
How do AI agents change big data tooling?
Agents act on data, so they need fresh, governed and well-described inputs. That raises the importance of the catalog and lineage layer, of event streams that can supply current context, and of access rules that apply to software as well as people. A decision made by an agent should be traceable to the data and policy behind it. ElixirData, XenonStack's Context OS, is the layer that keeps that context and policy together above the data stack.
What should you do first?
- List the tools you run today by layer and mark any that are retired or near end of life.
- Pick the one layer that causes the most cost or delay and review it against the six criteria.
- Keep data in an open table format so another engine can read it without a migration.
- Choose the catalog and put access and lineage rules there before adding engines.
- Name the first decision an agent will make on this data and check its inputs are governed.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What are the main categories of big data tools?
Storage and table formats, batch processing, stream processing, interactive SQL, event streaming, real-time analytics, orchestration and transformation, catalogs and governance, and managed warehouses or lakehouses.
Is Apache Sqoop still supported?
No. The Apache Attic page says Sqoop was retired in June 2021 and its move to the Attic was completed in July 2021.
Does Apache Kafka still need ZooKeeper?
No. The Kafka 4.0 announcement of 18 March 2025 describes it as the first major release to operate entirely without ZooKeeper, running in KRaft mode by default.
Is Hadoop still used?
Many organisations still run HDFS clusters. For new platforms, teams more often pair object storage with an open table format, but the right choice depends on your existing estate and data residency needs.
How do I avoid lock-in in a big data stack?
Keep data in an open table format on object storage, prefer catalogs with open APIs, and review the licence terms of each tool before standardising on it.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE