Key takeaway
- Data lakehouse architecture explained for enterprise teams: layers, Delta Lake vs Iceberg vs Hudi, governance, industry use cases and when not to use one.
What is a data lakehouse?
A data lakehouse is a data management system that keeps data in low-cost, directly accessible storage and adds warehouse features on top, such as ACID transactions, versioning, indexing and SQL query optimisation. That is the definition used in the Armbrust et al. (CIDR 2021) paper, and Databricks describes it in the same terms in its own documentation: "a data management system that combines the benefits of data lakes and data warehouses".
For enterprise leaders the practical question is not the label but whether one governed copy of data can serve BI, data science and AI agents without a second pipeline. This guide covers the layers, the open table formats, the governance and cost controls, where industries use it and when a lakehouse is the wrong choice. It builds on our guides to the governed data lake and the modern data warehouse.
How is a lakehouse different from a data lake and a data warehouse?
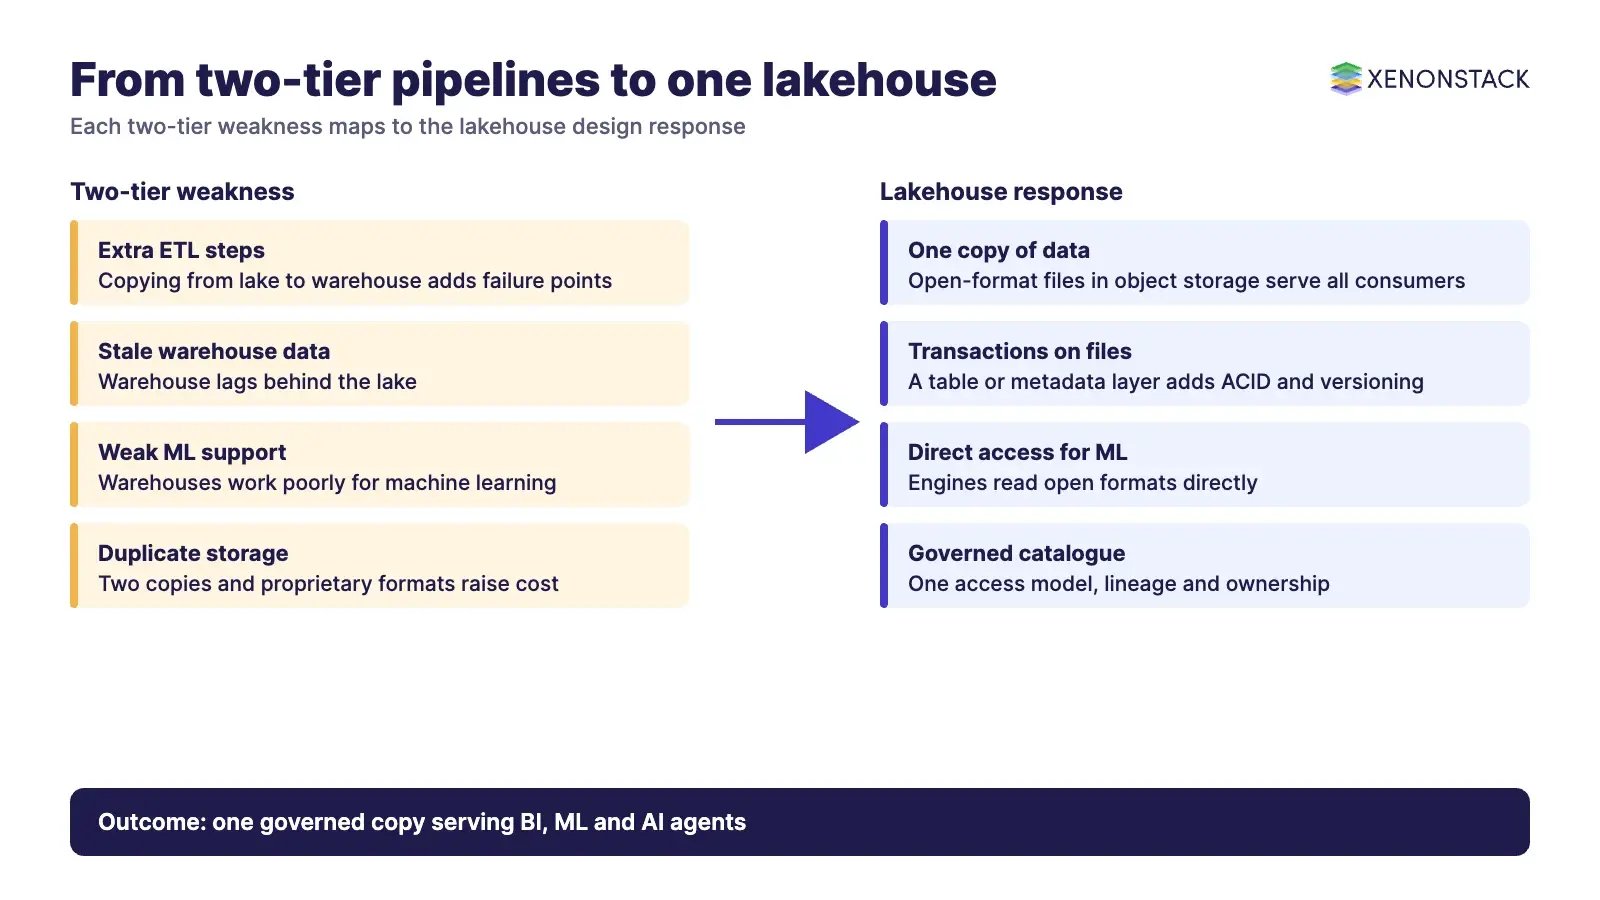
The paper above describes the two-tier pattern (a lake feeding a warehouse) and lists its weaknesses: ETL steps that add failure points, warehouse data that lags the lake, weak support for machine learning on warehouses, and the cost of duplicate storage and proprietary formats. A lakehouse tries to remove the second tier.
| Data lake | Data warehouse | Data lakehouse | |
|---|---|---|---|
| Storage | Object storage, files in open formats | Managed, often proprietary storage | Object storage, files in open formats |
| Data types | Structured, semi-structured, unstructured | Mainly structured | All three |
| Transactions and schema control | Not provided by plain files | Built in | Added by a table format or metadata layer (for example Delta Lake) |
| Typical consumers | Data engineering, data science | BI and SQL analysts | BI, SQL, data science and ML on one copy |
| Main risk | Ungoverned, inconsistent data | Cost and lock-in for varied data | Operational complexity and governance effort |
Sources: Armbrust et al. (CIDR 2021); Databricks documentation. The table is our summary of those sources, not a benchmark.
What layers make up a lakehouse architecture?
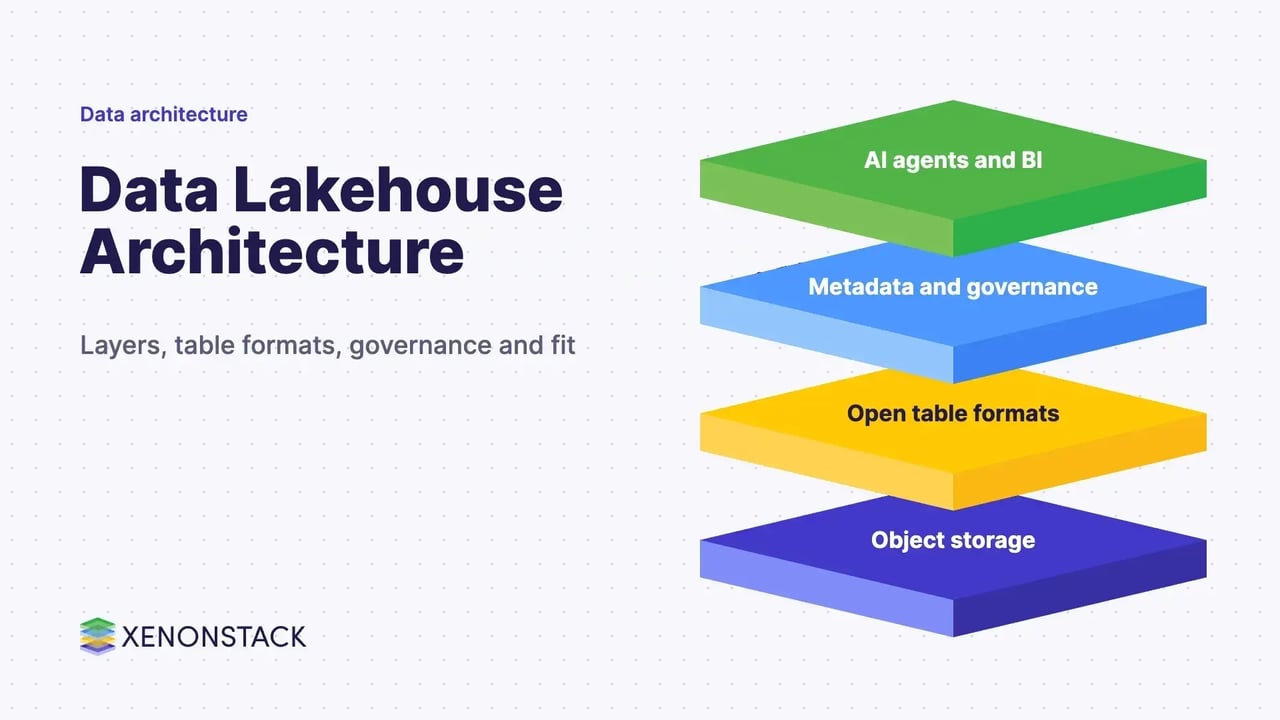
A lakehouse is usually described in five layers. The Databricks documentation places data in cloud object storage with a metadata layer on top, so one copy can serve ML, data engineering and BI.
| Layer | What it does | Decision to make |
|---|---|---|
| Ingestion | Brings batch and streaming data from internal and external sources into storage | Which sources are streamed and which are loaded in batches |
| Storage | Holds all data types in object storage using open file formats | Which open file and table format to standardise on |
| Metadata | Catalogue and transaction layer: ACID transactions, schema enforcement, versioning, lineage | Which catalogue is the single source of truth |
| API | Exposes the data to engines, tools and applications | Which engines and languages are supported |
| Consumption | BI dashboards, SQL queries, notebooks, ML jobs and AI agents | Who may query what, under which policy |
The metadata layer carries most of the weight. In Databricks documentation, Unity Catalog is described as "a unified, fine-grained governance solution for data and AI" that tracks lineage and applies one access model. Other platforms use their own catalogues, so check the one you plan to buy. For the catalogue side of the design, see our guide to metadata management.
Which open table format should you choose: Delta Lake, Iceberg or Hudi?
Open table formats add the transaction and metadata features that plain files lack. Each project describes itself differently, so read the primary page before a standards decision.
| Format | What its own site says | Where it fits |
|---|---|---|
| Delta Lake | ACID transactions, scalable metadata, unified batch and streaming, schema enforcement, time travel, upserts and deletes (Delta Lake documentation) | Spark-centred estates, including Databricks |
| Apache Iceberg | "A high-performance format for huge analytic tables"; schema evolution, hidden partitioning, time travel and rollback (Apache Iceberg site) | Estates that want several engines (Spark, Trino, Flink) on the same tables |
| Apache Hudi | Open table format with efficient upserts and deletes, incremental queries, clustering, compaction and indexing (Apache Hudi documentation) | Incremental pipelines with frequent record updates |
Engine and vendor support changes often, so confirm current support for your engines on each project page before committing.
What do governance, security and cost need in a lakehouse?
Putting every data type in one place raises the stakes on control. These are the questions an architecture review should settle:
- Access: one access model across tables, files and ML assets, with column and row rules for sensitive data.
- Lineage and audit: a record of where each table came from and who changed it. Table versioning (time travel) helps with audit and rollback, but it is not a substitute for lineage.
- Quality: schema enforcement at ingestion and tests on pipelines, so bad records do not reach BI or AI.
- Cost: object storage is typically cheaper than warehouse storage, but compute, small-file maintenance and duplicated copies still need owners and budgets.
Which industries use a data lakehouse?
The pattern fits any sector that mixes structured records with files, logs or sensor data. The table lists typical data sources, not outcomes we can quantify.
| Industry | Typical data brought together | Governance concern |
|---|---|---|
| Healthcare | Electronic health records, device data, imaging metadata | Patient privacy and consent rules |
| Financial services | Transactions, risk and market data, documents | Audit trail, model risk, retention |
| Retail | Point-of-sale, customer interactions, product feeds | Customer consent and data minimisation |
| Manufacturing | Sensor and machine data, supply-chain systems | Data ownership across plants and suppliers |
| Government | Tax, public-health and service records | Access by purpose, public accountability |
When is a lakehouse the wrong choice?
A lakehouse is not automatically better than two well-run tiers. Consider a different design when:
- your data is almost entirely structured and a managed warehouse already meets performance and cost needs;
- you lack the engineering capacity to run table maintenance, catalogue governance and access policy;
- one vendor-specific feature set would lock you in despite the open formats on paper;
- the workload is a single, narrow use case where a purpose-built store is simpler.
The CIDR paper is written by the Databricks founders and engineers, so treat its argument for replacing warehouses as one informed position, not a neutral verdict.
How should an organisation adopt a data lakehouse?
- Define the decisions the data must support: BI, ML, AI agents, regulatory reporting.
- Choose the storage, table format and catalogue: check engine support against the format pages above.
- Migrate one domain first: prove ingestion, quality tests and access policy on a single data domain.
- Set ownership: a named owner per dataset, with service levels for freshness and quality.
- Add consumers in stages: BI first, then data science, then agents.
- Monitor cost and quality continuously: compute spend, file maintenance, failed tests and access reviews.
How do AI agents use a lakehouse?
Agents need governed data and the context around it, not only storage. A lakehouse supplies the data; a decision layer must still say which policy applies and record what the agent did. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights. For platform-specific patterns, see our guides to agentic AI for data management and agentic AI with Snowflake, and our enterprise data lake services.
To map one data decision your agents should make, and the governed context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is a data lakehouse?
A data lakehouse is a data management system that keeps data in low-cost, directly accessible storage and adds warehouse features such as ACID transactions, versioning and SQL query optimisation, according to the CIDR 2021 paper.
How is a data lakehouse different from a data lake or a data warehouse?
A lake stores raw files without transactions, and a warehouse manages mostly structured data in its own storage. A lakehouse keeps open-format files in object storage and adds a table or metadata layer so one copy can serve BI and machine learning.
What are the layers of a lakehouse architecture?
Ingestion, storage, metadata, API and consumption. The metadata layer provides transactions, schema enforcement, versioning and governance.
What is the difference between Delta Lake, Apache Iceberg and Apache Hudi?
All three add table features to files in a lake. According to their own sites, Delta Lake offers ACID transactions and time travel, Iceberg offers schema evolution, hidden partitioning and rollback, and Hudi offers efficient upserts and incremental queries. Confirm engine support on each project page.
When should an organisation not use a data lakehouse?
When data is mostly structured and a managed warehouse already meets needs, when the team cannot run catalogue governance and table maintenance, or when the workload is one narrow use case.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE